How we help

Start with an urgent problem, one part, or the whole app.

Something is broken now

Your app is down, or logins, payments, data or secret keys have stopped working. Message me on LinkedIn and say it’s urgent. We deal with it within 24 hours. If the problem is in an area we cover, we get it running safely first.

Start with one part

Start where it matters most right now: payments, your data, a launch, a sale or an investor’s questions. It’s faster than the full sprint. We agree the exact timing on the call.

The 13 areas

What the sprint covers

For each check, you can see the work we do, why it matters and how we check it.

Logins & who sees what

Authentication & authorization

Give every user the right access, and keep privileged actions protected.

11 checks · All included

Start with this part
  1. 1.1

    Complete authentication flow review

    What we do
    Review and fix signup, login, logout, password reset, email verification, and OAuth callbacks.
    Why it matters
    Broken account flows can lock out customers or allow unauthorized access.
    How we check it
    Exercise successful, rejected, expired, and reused-token paths for each supported flow.
  2. 1.2

    Session and token controls

    What we do
    Verify expiry, refresh, and session revocation on logout and password change.
    Why it matters
    An old session can remain usable after an account owner tries to secure it.
    How we check it
    Confirm expired and revoked sessions cannot continue accessing protected resources.
  3. 1.3

    Server-side authorization

    What we do
    Enforce permissions on every protected route, API endpoint, and server action.
    Why it matters
    A hidden button does not prevent a direct request to the backend.
    How we check it
    Call protected actions directly as unauthorized and underprivileged users; confirm rejection.
  4. 1.4

    Data isolation across every table

    What we do
    Implement and test Row-Level Security or equivalent server-side scoping across all tables, with explicit rules for intentionally public data.
    Why it matters
    Missing data boundaries can expose one customer's records to another.
    How we check it
    Run read and write tests as anonymous users, different roles, and separate tenants.
  5. 1.5

    Protected administrative actions

    What we do
    Restrict admin routes and operations to explicit, verified roles.
    Why it matters
    Unprotected administrative actions can let ordinary accounts change or delete important data.
    How we check it
    Test administrative operations using both authorized and ordinary accounts.
  6. 1.6

    Authentication abuse protection

    What we do
    Implement rate limits and brute-force protections on authentication and recovery endpoints.
    Why it matters
    Automated login attempts can compromise accounts or overwhelm account services.
    How we check it
    Simulate repeated attempts and verify limits, responses, and normal-user recovery.
  7. 1.7

    Documented role model

    What we do
    Write a one-page matrix defining roles and their permitted actions.
    Why it matters
    Ambiguous permissions create inconsistent behavior as the product grows.
    How we check it
    Compare the role matrix with tested backend permissions.
  8. 1.8

    Complete account deletion

    What we do
    Build the account deletion flow, covering related records and stored assets under the documented retention rules.
    Why it matters
    Removing a profile alone can leave personal data scattered through the system.
    How we check it
    Delete a seeded account and inspect its related records, files, and recorded retention exceptions.
  9. 1.9

    Session management and global sign-out

    What we do
    Provide session listing and a way to sign out across all active sessions.
    Why it matters
    Users need a way to remove access from lost devices or unfamiliar sessions.
    How we check it
    Create multiple sessions, revoke them, and confirm protected access stops.
  10. 1.10

    Sensitive-action audit log

    What we do
    Log role changes, deletions, and billing changes with the actor, action, and time; protect access to the log.
    Why it matters
    Important changes are difficult to investigate without a reliable activity record.
    How we check it
    Trigger the listed actions and verify accurate, access-controlled audit entries.
  11. 1.11

    Two-factor authentication for owner and admin accounts

    What we do
    Enforce a second factor on every owner and admin account, in the application and on every provider dashboard behind it, with recovery codes stored in the owner's vault.
    Why it matters
    One leaked password on a dashboard account is a full takeover of the product and its data.
    How we check it
    Attempt sign-in to each owner and admin account without the second factor and confirm it is refused.

Secret keys & ownership

Secrets, keys & configuration

Keep privileged credentials out of browsers, repositories, and accidental test activity.

9 checks · All included

Start with this part
  1. 2.1

    Frontend secret removal

    What we do
    Remove all private secrets from frontend code and downloadable bundles, relocating their use to server-side code.
    Why it matters
    Exposed private credentials can let others access services using your permissions.
    How we check it
    Scan source and built assets and inspect browser traffic for private credentials.
  2. 2.2

    Repository history scan and rotation

    What we do
    Scan Git history for committed secrets and rotate every exposed credential found.
    Why it matters
    Deleting a secret from the latest commit leaves earlier copies accessible.
    How we check it
    Retain scan results and confirm exposed credentials have been invalidated and replacements work.
  3. 2.3

    Server-only administrative keys

    What we do
    Verify service-role and administrative keys are used exclusively in protected server environments.
    Why it matters
    Administrative keys can bypass the data protections intended for ordinary users.
    How we check it
    Check runtime configuration, built assets, and each code path using administrative credentials.
  4. 2.4

    Environment configuration separation

    What we do
    Separate development, staging, and production variables, databases, and keys; document the configuration inventory.
    Why it matters
    Testing with live credentials can affect real customer data and transactions.
    How we check it
    Inspect environment mappings and confirm staging actions stay within staging services.
  5. 2.5

    Protected third-party API usage

    What we do
    Move private AI, email, SMS, and other service keys server-side and implement usage caps.
    Why it matters
    Abused endpoints can consume paid services on your account.
    How we check it
    Test unauthorized calls, per-user limits, and configured usage ceilings.
  6. 2.6

    Secret rotation runbook

    What we do
    Document how to rotate each key, update its dependents, verify the change, and recover from a failed rotation.
    Why it matters
    An urgent rotation becomes harder when nobody knows which services depend on a key.
    How we check it
    Rehearse rotation with a test credential and record the affected services and checks.
  7. 2.7

    Metered-service spend alerts

    What we do
    Configure spend or usage alerts for every metered API, using provider alerts or application-side measurement.
    Why it matters
    Unexpected consumption can continue unnoticed until the next invoice.
    How we check it
    Trigger a test threshold and confirm the alert reaches the designated owner.
  8. 2.8

    Provider account ownership

    What we do
    Move every service the product depends on (database, hosting, payments, email, AI, domain) into an account the founder owns, with the founder as the owner role, billing in the founder's name, and any previous builder removed.
    Why it matters
    AI-built apps are often wired to accounts the builder created. The business does not control what it does not own.
    How we check it
    Produce an inventory listing each provider, the owning account, the owner role holder, and the date the previous builder's access was removed.
  9. 2.9

    Managed-platform security settings

    What we do
    Review and harden the settings of every managed service in the stack: auth policies, storage access rules, privileged keys kept server-side, and a plan tier adequate for backups and recovery.
    Why it matters
    Managed platforms ship permissive defaults so that prototypes work. Those defaults are what leaks data in production.
    How we check it
    Record the before-and-after settings for each managed service, naming each risky default and its new value.

Security & abuse protection

Input, output & application security

Protect the application's public entry points and test them from an attacker's perspective.

12 checks · All included

Start with this part
  1. 3.1

    Server-side request validation

    What we do
    Validate every data-writing endpoint with explicit schemas and safe input/output handling, including injection defenses.
    Why it matters
    Malformed or hostile inputs can corrupt records or reach other users' screens.
    How we check it
    Submit invalid and hostile payloads and confirm safe rejection or handling.
  2. 3.2

    Secure file uploads

    What we do
    Validate upload types and sizes, enforce bucket permissions, and protect access to stored files.
    Why it matters
    Weak upload and storage controls can expose documents or accept unsafe files.
    How we check it
    Test disallowed formats, oversized files, unauthorized downloads, and storage listings.
  3. 3.3

    Restricted cross-origin access

    What we do
    Restrict CORS to intended origins and check credentialed request behavior alongside authentication and request-forgery protections.
    Why it matters
    Overly permissive cross-origin access can expose authenticated responses to untrusted websites.
    How we check it
    Test approved and unapproved origins, credential handling, and state-changing request protections.
  4. 3.4

    Production security headers

    What we do
    Configure and test CSP, HSTS, framing restrictions, and other appropriate browser security headers.
    Why it matters
    Missing browser protections can increase exposure to script injection, framing attacks, or insecure connections.
    How we check it
    Inspect response headers and exercise the application to confirm intended protections without broken flows.
  5. 3.5

    Dependency remediation

    What we do
    Audit dependencies, upgrade or remove known-vulnerable packages, and remove unused packages.
    Why it matters
    Published package vulnerabilities can remain reachable in an otherwise functional product.
    How we check it
    Record the dependency scan, remediation, and regression checks after changes.
  6. 3.6

    Public-endpoint rate limits

    What we do
    Protect public forms, signup flows, and resource-consuming endpoints with appropriate limits.
    Why it matters
    Abuse can create spam, availability problems, and unexpected service bills.
    How we check it
    Simulate bursts and verify enforcement without blocking ordinary use.
  7. 3.7

    OWASP Top 10 review

    What we do
    Review the application against the OWASP Top 10 and record findings, fixes, and evidence by category.
    Why it matters
    Unexamined application risks leave preventable weaknesses in the production foundation.
    How we check it
    Deliver category-level results and supporting test evidence, with justified non-applicable cases identified.
  8. 3.8

    Bot protection

    What we do
    Add bot protection to public forms using Turnstile, hCaptcha, or an appropriate equivalent.
    Why it matters
    Automated submissions can pollute accounts, reporting, and outbound communication.
    How we check it
    Confirm valid users can submit and rejected or missing bot challenges are handled safely.
  9. 3.9

    Security disclosure contact

    What we do
    Publish security.txt and a monitored disclosure contact for vulnerability reports.
    Why it matters
    A researcher needs a clear way to report an issue to the right person.
    How we check it
    Check the published file, contact details, and delivery of a test message.
  10. 3.10

    Targeted external penetration testing

    What we do
    Test the five highest-risk externally reachable attack surfaces, remediate findings, and deliver the methods and evidence.
    Why it matters
    Implementation review alone may miss behavior exposed through real attack paths.
    How we check it
    Record the five surfaces, authorized tests, findings, fixes, and retest outcomes. AxonBuild performs this targeted test.
  11. 3.11

    AI feature hardening

    What we do
    For every model-backed feature: prompt-injection defences, validation of model output before it touches data or users, per-user usage limits, and a timeout with a fallback when the provider is down.
    Why it matters
    Model calls are a new input surface. Unbounded ones leak data, run up bills, and fail loudly when the provider does.
    How we check it
    Run injection test cases against each feature, a spend simulation that hits the limit, and a provider-outage simulation in staging.
  12. 3.12

    Edge protection

    What we do
    Place a CDN or web application firewall in front of the origin, with rate and abuse rules that absorb floods before they reach the application.
    Why it matters
    Application-layer bot protection never sees a volumetric flood; it takes the app down first.
    How we check it
    Send a load burst at the edge and confirm it is absorbed while the origin's health endpoint stays green.

Your data & backups

Database & data

Keep records consistent, queries efficient, and recovery practical.

14 checks · All included

Start with this part
  1. 4.1

    Schema integrity review

    What we do
    Review and correct types, nullability, foreign keys, uniqueness rules, and cascade behavior.
    Why it matters
    Inconsistent relationships create broken workflows and unreliable reports.
    How we check it
    Test rejected invalid records and expected relationship behavior using representative data.
  2. 4.2

    Foreign-key and query indexing

    What we do
    Review every foreign key and hot query path with execution plans and implement appropriate indexes.
    Why it matters
    Missing useful indexes can make ordinary requests expensive as data grows.
    How we check it
    Retain before-and-after query plans and timings; document the index decisions.
  3. 4.3

    N+1 query removal

    What we do
    Replace repeated per-record lookups with appropriate joins, batching, or prefetching.
    Why it matters
    Fetching a list can create unnecessary database traffic and slow responses.
    How we check it
    Measure database query counts for representative list and detail views.
  4. 4.4

    Atomic multi-step writes

    What we do
    Wrap related database changes in transactions and protect workflows spanning several writes.
    Why it matters
    A partial operation can leave users, orders, or workspaces in inconsistent states.
    How we check it
    Inject a failure between writes and verify atomic rollback or the documented recovery behavior.
  5. 4.5

    Connection pooling

    What we do
    Configure connection pooling or the platform's equivalent connection management and test it under load.
    Why it matters
    Connection exhaustion can make the database unavailable during busy periods.
    How we check it
    Run concurrent requests and record connection usage, errors, and pool configuration.
  6. 4.6

    Version-controlled migrations

    What we do
    Move schema changes into ordered migrations committed to the repository.
    Why it matters
    Untracked dashboard changes make environments difficult to reproduce and maintain.
    How we check it
    Apply the migration sequence to a clean test database and compare the resulting schema.
  7. 4.7

    Verified backups and restore

    What we do
    Verify automated backups, set retention, and perform a real restore test.
    Why it matters
    A backup only helps if it exists and can be restored successfully.
    How we check it
    Restore a backup into an isolated environment and check representative data integrity.
  8. 4.8

    Consistent time handling

    What we do
    Standardize event timestamps in UTC and document local-date and display-time behavior.
    Why it matters
    Inconsistent time handling can distort billing schedules, reporting, and user expectations.
    How we check it
    Test timestamps across time zones and relevant date boundaries.
  9. 4.9

    Recoverable deletion

    What we do
    Implement soft deletion where the product needs recovery, consistently with account-erasure and retention rules.
    Why it matters
    Accidental deletion should be recoverable where the business workflow requires it.
    How we check it
    Delete and restore a test entity and verify normal queries exclude deleted records.
  10. 4.10

    Staging seed data

    What we do
    Provide a repeatable seed script with realistic non-sensitive test records.
    Why it matters
    An empty staging system gives the team little opportunity to test realistic workflows.
    How we check it
    Run the seed process on a clean staging database and exercise core flows.
  11. 4.11

    Orphaned-record cleanup

    What we do
    Identify and clean abandoned records and broken relationships with documented safeguards.
    Why it matters
    Unnecessary data complicates exports, reporting, maintenance, and storage.
    How we check it
    Run a dry-run comparison and confirm the cleanup preserves valid linked records.
  12. 4.12

    Disaster recovery drill

    What we do
    Restore the application and data into a fresh environment, time the recovery, and document the procedure.
    Why it matters
    Your team needs evidence of recovery time before a real incident.
    How we check it
    Record the timed drill, recovered services, integrity checks, and observed recovery limits.
  13. 4.13

    Data model diagram

    What we do
    Deliver a readable diagram of entities, relationships, and ownership boundaries for the data room.
    Why it matters
    Technical reviewers and future engineers need a quick way to understand the data.
    How we check it
    Compare the diagram against the delivered schema and migrations.
  14. 4.14

    File storage lifecycle

    What we do
    Use signed, expiring links for private files, enforce size and type limits, scan user uploads for malware, and set a retention rule for uploads.
    Why it matters
    File buckets are the most common place an AI-built app is publicly readable without anyone noticing.
    How we check it
    Fetch a private file without a signed link and confirm refusal; upload an oversized and a disallowed file and confirm rejection. Upload a safe malware-scanner test file and confirm rejection. Verify that expired uploads are removed according to the configured retention rule.

Payments

Payments & billing

Keep payment events, subscriptions, and product access in agreement.

10 checks · All included

Start with this part
  1. 5.1

    Webhook signature verification

    What we do
    Verify the payment provider's signatures before processing webhook payloads.
    Why it matters
    Forged events can wrongly grant paid access or change account state.
    How we check it
    Confirm valid events succeed and invalid or altered payloads are rejected.
  2. 5.2

    Idempotent webhook handling

    What we do
    Make every webhook handler safe to repeat, including concurrent delivery and its downstream side effects.
    Why it matters
    Repeated events can duplicate fulfillment or corrupt subscription state if processed unsafely.
    How we check it
    Replay and concurrently deliver events; confirm one intended business effect.
  3. 5.3

    Complete billing event lifecycle

    What we do
    Handle creation, updates, cancellation, payment failure, refunds, and disputes, including delayed or out-of-order events.
    Why it matters
    Missing lifecycle handling can leave paid access inconsistent with billing.
    How we check it
    Test the relevant lifecycle transitions and verify the final account state.
  4. 5.4

    Server-side entitlements

    What we do
    Enforce paid-plan permissions and usage limits in backend actions.
    Why it matters
    Client-side plan labels alone do not protect paid functionality.
    How we check it
    Attempt paid operations with free, expired, and valid paid accounts.
  5. 5.5

    Separated payment environments

    What we do
    Verify test and live credentials are isolated by environment.
    Why it matters
    Misconfigured environments can process real charges during testing or accept no real payments in production.
    How we check it
    Inspect provider accounts and run isolated test-mode transactions.
  6. 5.6

    Billing reconciliation check

    What we do
    Compare the application's billing records with the payment provider and correct mismatches.
    Why it matters
    Undetected drift creates access and revenue-reporting inconsistencies.
    How we check it
    Seed mismatched records and verify they are identified and reconciled correctly.
  7. 5.7

    Failed-payment recovery

    What we do
    Implement grace periods and dunning messages consistent with the product's billing rules.
    Why it matters
    Payment failures need a clear recovery path for customers and predictable access behavior.
    How we check it
    Simulate payment failure, notice delivery, recovery, and grace-period expiry.
  8. 5.8

    Customer billing portal

    What we do
    Connect Stripe Customer Portal or the existing provider's equivalent for invoices, card changes, and supported plan management.
    Why it matters
    Routine billing changes otherwise require manual support.
    How we check it
    Test an authenticated customer's portal access and resulting updates in the application.
  9. 5.9

    Scheduled reconciliation

    What we do
    Run recurring reconciliation and alert the team to billing discrepancies.
    Why it matters
    A one-time check will not catch drift introduced after future changes.
    How we check it
    Execute the scheduled job against test mismatches and verify its alert and output.
  10. 5.10

    Billing operations runbook

    What we do
    Document refunds, complimentary access, and dispute handling in the application's payment setup.
    Why it matters
    The team needs clear procedures when a billing question becomes urgent.
    How we check it
    Walk through the procedures in test mode and identify the responsible account permissions.

Errors & recovery

Error handling & reliability

Keep failures visible, recoverable, and contained.

10 checks · All included

Start with this part
  1. 6.1

    Consistent exception handling

    What we do
    Remove swallowed failures and empty catch blocks, replacing them with deliberate recovery or useful error reporting.
    Why it matters
    Silent failures can make an unsuccessful operation look complete.
    How we check it
    Inject failures and verify accurate responses and diagnostic records.
  2. 6.2

    Backend handlers and frontend boundaries

    What we do
    Implement global backend error handling and frontend error boundaries with clear recovery states.
    Why it matters
    A localized failure should not leave the customer with an unexplained blank page.
    How we check it
    Trigger server and component errors and confirm safe responses and contained UI failures.
  3. 6.3

    Error tracking

    What we do
    Install error tracking such as Sentry with protected source maps, environment labels, and alerts.
    Why it matters
    Customer complaints should not be the only way you discover application faults.
    How we check it
    Send a test error and verify symbolication, environment attribution, and alert delivery.
  4. 6.4

    External-call timeouts

    What we do
    Set deliberate timeouts for AI, email, payment, and other external calls.
    Why it matters
    Slow providers can leave requests and workers waiting indefinitely.
    How we check it
    Simulate a slow dependency and confirm bounded waits and a useful failure state.
  5. 6.5

    Retries with backoff

    What we do
    Add bounded retries with backoff to transient failures where repeating the operation is safe.
    Why it matters
    Temporary failures need recovery without creating duplicate actions or retry storms.
    How we check it
    Simulate transient and persistent failures and verify retry limits and side effects.
  6. 6.6

    Background processing

    What we do
    Move long-running AI generation, exports, and bulk communication into background jobs.
    Why it matters
    Lengthy work can exceed request limits or be interrupted when a browser disconnects.
    How we check it
    Run a long task beyond the normal request window and verify completion and user-visible status.
  7. 6.7

    Reliable job execution

    What we do
    Make jobs idempotent and provide a dead-letter or failed-job path with a recovery procedure.
    Why it matters
    Retries can duplicate actions, while discarded failures leave work unfinished.
    How we check it
    Replay jobs, exhaust retries, and verify one intended result plus a recoverable failure record.
  8. 6.8

    Graceful degradation

    What we do
    Keep unaffected functions usable when an external service is unavailable.
    Why it matters
    One provider outage should not unnecessarily block the entire application.
    How we check it
    Disable an integration and check its fallback plus unaffected customer journeys.
  9. 6.9

    Health endpoint

    What we do
    Provide a safe health endpoint reporting the readiness of required services without exposing secrets.
    Why it matters
    Monitoring needs a reliable signal for whether the application can serve requests.
    How we check it
    Check healthy and degraded responses and confirm sensitive details are not public.
  10. 6.10

    Staging outage simulation

    What we do
    Simulate AI or payment-provider failure in staging and verify the expected recovery behavior.
    Why it matters
    Fallback code needs to be exercised before customers depend on it.
    How we check it
    Record outage scenarios, queue behavior, customer messages, and recovery results.

Updates & releases

Environments, CI/CD & deployment

Make releases repeatable and give the team a tested way back.

13 checks · All included

Start with this part
  1. 7.1

    Three isolated environments

    What we do
    Provide development, staging, and production with separate databases, credentials, and configuration.
    Why it matters
    Routine tests should not change real customer records or trigger live transactions.
    How we check it
    Verify service isolation and perform a staging action without a production side effect.
  2. 7.2

    Protected production branch

    What we do
    Protect the main branch with required checks and controlled merge permissions.
    Why it matters
    Unchecked changes can otherwise bypass the release process.
    How we check it
    Attempt a failing merge and confirm the protection prevents it.
  3. 7.3

    Pull-request CI

    What we do
    Run linting, type checks, builds, and tests on every pull request.
    Why it matters
    Automated checks catch regressions before changes reach customers.
    How we check it
    Submit failing and passing changes and retain the CI results.
  4. 7.4

    Staging deployment and production promotion

    What we do
    Automate staging deployment and require an explicit promotion step for production.
    Why it matters
    A repeatable release path removes reliance on one person's manual routine.
    How we check it
    Deploy a change to staging, then demonstrate the production promotion gate.
  5. 7.5

    Migration-aware deployment

    What we do
    Integrate database migrations into the deployment process with ordering and compatibility checks.
    Why it matters
    Application code can fail when its expected schema is missing or incompatible.
    How we check it
    Deploy a representative schema change and verify sequencing and failure handling.
  6. 7.6

    Tested rollback

    What we do
    Document and rehearse release rollback, including how database changes are handled safely.
    Why it matters
    A failed release needs a recovery path the team has already practiced.
    How we check it
    Roll back a test release and verify application behavior and retained data.
  7. 7.7

    Pull-request previews

    What we do
    Provide browser-accessible preview deployments for pull requests with isolated test configuration.
    Why it matters
    Reviewers need to inspect a change before it joins the release branch.
    How we check it
    Open a preview from a test pull request and verify its environment isolation.
  8. 7.8

    Contribution guide and PR template

    What we do
    Provide a short contributing guide and a template covering the change, verification, and release considerations.
    Why it matters
    Consistent review information makes future development easier to assess.
    How we check it
    Create a pull request using the template and follow the guide on a clean checkout.
  9. 7.9

    Automated dependency updates

    What we do
    Configure Renovate, Dependabot, or an equivalent to propose dependency updates with checks.
    Why it matters
    Routine security and maintenance updates need a repeatable path to review.
    How we check it
    Verify an update proposal triggers the appropriate CI checks and review requirements.
  10. 7.10

    Timed deployment

    What we do
    Optimize and document the deployment pipeline to complete a representative release in under ten minutes.
    Why it matters
    A slow release process delays delivery of urgent fixes.
    How we check it
    Time the agreed deployment path and record its start, finish, and included steps.
  11. 7.11

    Independent repository and hosting

    What we do
    Keep the application in a version-controlled repository and on a hosting account the founder controls, deployable through a documented pipeline, independent of the tool that generated it.
    Why it matters
    An app that only exists inside the builder tool cannot be reviewed, rolled back, or handed to another engineer.
    How we check it
    Deploy a fresh clone to staging through the pipeline with no step that depends on the generating tool.
  12. 7.12

    Feature flags and kill switches

    What we do
    Add a flag mechanism for risky features and third-party dependencies so any one of them can be turned off without a deployment.
    Why it matters
    The fastest fix for a broken release is switching the feature off.
    How we check it
    Disable a flagged feature in production and confirm the product stays usable with the feature hidden.
  13. 7.13

    Domain, DNS and TLS hygiene

    What we do
    Enforce HTTPS everywhere with HSTS and a CAA record, lock the registrar, document the DNS records, and confirm renewal ownership.
    Why it matters
    An expired domain or a misissued certificate is an outage no code fix repairs.
    How we check it
    Pass an external TLS scan at the top grade and file a DNS record export in the runbooks.

Alerts

Logging, monitoring & alerting

Give the team an operational view and alerts they can act on.

8 checks · All included

Start with this part
  1. 8.1

    Structured, sanitized logs

    What we do
    Add structured request logs with correlation IDs and appropriate user references; exclude passwords, tokens, and unnecessary personal data.
    Why it matters
    Useful traces need to support investigation without creating another data leak.
    How we check it
    Trace a test request across services and check log content for sensitive fields.
  2. 8.2

    Uptime monitoring

    What we do
    Monitor the production URL and health endpoint with outage alerts.
    Why it matters
    A public outage can go unnoticed without independent checks.
    How we check it
    Trigger a controlled check failure and verify notification and recovery reporting.
  3. 8.3

    Operational threshold alerts

    What we do
    Alert on error spikes, latency, connection pressure, and queue backlog.
    Why it matters
    Gradual degradation needs attention before it becomes a broad outage.
    How we check it
    Trigger each configured condition and record its alert threshold and behavior.
  4. 8.4

    Actionable alert routing

    What we do
    Route alerts to the designated Slack or email destination and tune thresholds to reduce noise.
    Why it matters
    An alert is only useful if the responsible person sees and understands it.
    How we check it
    Send test alerts and verify their destination, context, and response instructions.
  5. 8.5

    Log retention

    What we do
    Set and document log retention across the application's services.
    Why it matters
    Retention that is too short impairs investigation; uncontrolled retention increases cost and exposure.
    How we check it
    Inspect the configured windows and verify retention behavior in supported systems.
  6. 8.6

    Core product analytics

    What we do
    Instrument signup, activation, core actions, and payment-funnel events with consent-aware collection.
    Why it matters
    The team needs to see where customers progress or encounter friction.
    How we check it
    Run core journeys and verify event names, properties, and consent behavior.
  7. 8.7

    Public status page

    What we do
    Provide a status page for service availability and incident communication.
    Why it matters
    Customers need a central place to understand an interruption.
    How we check it
    Publish a test incident and verify the page remains reachable separately from the app.
  8. 8.8

    Unified operations dashboard

    What we do
    Create one view of uptime, error rate, latency, signups, and revenue for the application's relevant services.
    Why it matters
    Checking the health of the business should not require piecing together several tools.
    How we check it
    Compare the displayed metrics with their source systems and verify refresh behavior.

Speed under load

Performance

Measure what the application can handle and improve the bottlenecks that matter.

7 checks · All included

Start with this part
  1. 9.1

    Appropriate caching

    What we do
    Cache repeated reads where it is safe, with explicit invalidation and customer-data boundaries.
    Why it matters
    Repeated expensive work wastes resources; unsafe caches can expose stale or private data.
    How we check it
    Compare cache hits and misses, test invalidation, and verify tenant separation.
  2. 9.2

    Load test and bottleneck fixes

    What we do
    Simulate concurrent users, identify the first bottlenecks, fix them, and rerun the workload.
    Why it matters
    Launch capacity should be measured before real traffic becomes the test.
    How we check it
    Report the workload, duration, environment, concurrency, latency, and error rate before and after changes.
  3. 9.3

    Bundle optimization and lazy loading

    What we do
    Reduce unnecessary frontend code and load routes or features when needed.
    Why it matters
    Large initial downloads slow first use, especially on constrained devices.
    How we check it
    Compare built bundle sizes and test route loading with representative network conditions.
  4. 9.4

    Image optimization

    What we do
    Optimize image dimensions, formats, compression, and delivery while preserving useful quality.
    Why it matters
    Oversized assets waste bandwidth and slow customer-facing pages.
    How we check it
    Compare transferred sizes and inspect rendered images at intended display dimensions.
  5. 9.5

    Lighthouse performance review

    What we do
    Run Lighthouse on representative pages, implement performance and accessibility improvements, and deliver a passing result against recorded acceptance targets.
    Why it matters
    Slow or difficult-to-use pages create avoidable friction.
    How we check it
    Report the chosen pages, device profile, numerical targets, and final results; manually check key accessibility interactions.
  6. 9.6

    Written capacity statement

    What we do
    Document measured concurrent capacity on the current infrastructure and the changes needed to plan for five times that workload.
    Why it matters
    A number without its conditions is a poor basis for growth decisions.
    How we check it
    Link capacity claims to load-test evidence and identify untested projections as projections.
  7. 9.7

    Accessibility baseline

    What we do
    Bring the core flows to WCAG AA: keyboard navigation, contrast, labels, and focus order.
    Why it matters
    Enterprise and public-sector buyers require it, and generated interfaces fail it by default.
    How we check it
    Score 100 on an automated accessibility audit of the core pages and complete a keyboard-only walk through signup, checkout, and the main task.

Safe code changes

Code health & AI development guardrails

Make the application easier for your team and AI tools to change safely.

11 checks · All included

Start with this part
  1. 10.1

    Dead code and duplicate logic cleanup

    What we do
    Remove dead code and consolidate duplicated logic while preserving required behavior.
    Why it matters
    Repeated implementations make it easy to fix one path and leave another broken.
    How we check it
    Record removed or consolidated code and run regression checks on affected flows.
  2. 10.2

    Consistent state management

    What we do
    Consolidate conflicting state ownership into a documented, consistent pattern.
    Why it matters
    Competing sources of truth can show different values in different screens.
    How we check it
    Exercise refreshes, mutations, and navigation and verify consistent displayed and stored state.
  3. 10.3

    Typed API boundaries

    What we do
    Define types at every API boundary and share contracts between frontend and backend using the stack's appropriate tooling.
    Why it matters
    Uncoordinated schema changes can break clients silently.
    How we check it
    Introduce a deliberate contract mismatch and confirm type or contract checks catch it.
  4. 10.4

    Documented repository structure

    What we do
    Organize the codebase consistently and explain its layout in the README.
    Why it matters
    Future developers and AI tools need to know where responsibilities belong.
    How we check it
    Follow the README from a clean checkout and trace a core feature through its documented modules.
  5. 10.5

    Critical-path smoke tests

    What we do
    Automate smoke tests for signup, login, the core product action, and payment flows.
    Why it matters
    A small change can break a business-critical journey elsewhere.
    How we check it
    Run the suite in CI and demonstrate that an intentional regression fails it.
  6. 10.6

    Strict typing

    What we do
    Enable TypeScript strict mode and resolve errors in TypeScript applications, with an equivalent strict-checking approach for other supported stacks.
    Why it matters
    Stronger checks catch classes of mistakes before execution.
    How we check it
    Record the strict configuration and a clean checking run without suppressing the errors being fixed.
  7. 10.7

    Auth and billing unit tests

    What we do
    Add unit tests around authorization and payment logic, including negative and edge cases.
    Why it matters
    Sensitive decisions need a reliable safety net when the implementation changes.
    How we check it
    Run the tests and show rejection of unauthorized access and incorrect billing transitions.
  8. 10.8

    AI repository guardrails

    What we do
    Provide CLAUDE.md, AGENTS.md, Cursor rules, or equivalents describing conventions and protected patterns; add CI checks for enforceable rules.
    Why it matters
    Future AI-assisted changes can undo hardening unless the workflow checks them.
    How we check it
    Review the guidance and demonstrate CI catching a representative forbidden regression.
  9. 10.9

    Recorded codebase tour

    What we do
    Record a 20–30-minute walkthrough of the repository, data model, and key architectural decisions.
    Why it matters
    A future engineer should not have to rediscover the system from scratch.
    How we check it
    Deliver an accessible recording with chapter markers or a short contents list.
  10. 10.10

    Reproducible local development setup

    What we do
    Provide one documented command that brings the application up locally, with an environment example and seed data.
    Why it matters
    The next engineer's first hour decides whether they can work on the product at all. Generated apps rarely have this.
    How we check it
    Go from clone to running application on a new machine by following the guide alone.
  11. 10.11

    Open-source licence audit

    What we do
    Inventory the licences of every dependency, flag copyleft or unlicensed packages, and replace or approve each one.
    Why it matters
    Licence questions are on every technical due diligence list, and generated apps pull packages without checking.
    How we check it
    Include the licence report in the due diligence pack with zero unresolved flags.

Emails

Email & communications

Make account and transaction messages traceable and maintain the sending setup.

3 checks · All included

Start with this part
  1. 11.1

    Sending-domain authentication

    What we do
    Verify and configure SPF, DKIM, and DMARC for the transactional sending domain.
    Why it matters
    Domain-authentication problems can undermine legitimate email delivery.
    How we check it
    Inspect DNS and received message headers for the configured authentication results.
  2. 11.2

    Transactional delivery tracking

    What we do
    Configure a dedicated transactional provider with delivery tracking for account and transaction messages.
    Why it matters
    Untracked failures make it difficult to know whether a customer received a critical message.
    How we check it
    Trigger each critical message type and confirm provider records and expected recipient delivery.
  3. 11.3

    Bounce and complaint handling

    What we do
    Process bounces and complaints and suppress further sending where appropriate.
    Why it matters
    Repeated sending to invalid or complaining recipients can damage sending reputation.
    How we check it
    Simulate provider events and verify suppression and subsequent send behavior.

Privacy & personal data

Privacy & compliance foundations

Implement the technical controls and documentation needed to handle personal data deliberately.

8 checks · All included

Start with this part
  1. 12.1

    Personal-data inventory

    What we do
    Document what personal data is stored, where it lives, why it is collected, and who can access it.
    Why it matters
    The team needs a reliable record when a customer or reviewer asks about data use.
    How we check it
    Trace a sample user through storage, logs, and providers and compare it with the inventory.
  2. 12.2

    Data export and deletion paths

    What we do
    Implement authenticated export and deletion workflows covering related systems and documented retention exceptions.
    Why it matters
    Personal-data requests are difficult to fulfill when the application has no reliable mechanism.
    How we check it
    Export and delete a seeded user's data; verify completeness, authorization, and recorded exceptions.
  3. 12.3

    Privacy and terms alignment

    What we do
    Verify privacy and terms links and review the stated data practices against the application; document and resolve technical discrepancies with the owner.
    Why it matters
    The public description of data use should match what the product actually does.
    How we check it
    Compare the policy statements with the data inventory and provider flows and record the owner-approved alignment.
  4. 12.4

    Cookie consent controls

    What we do
    Implement consent controls for the application's audience and tracking configuration, including EU visitors where relevant.
    Why it matters
    Optional tracking needs to follow the user's recorded consent choices.
    How we check it
    Test consent, refusal, withdrawal, and persistence; verify optional scripts respect those choices.
  5. 12.5

    Data retention policy

    What we do
    Document retention periods and handling rules for logs, user history, and abandoned records.
    Why it matters
    Keeping data without a defined purpose makes storage and data handling harder to govern.
    How we check it
    Review the schedule against the data inventory and the configured lifecycle controls.
  6. 12.6

    SOC 2-style controls checklist

    What we do
    Deliver a technical controls checklist with supporting evidence organized for enterprise security review.
    Why it matters
    Enterprise buyers need evidence of how the application is protected and operated.
    How we check it
    Link each documented control to its owner, configuration, or test evidence. This deliverable is not a SOC 2 audit report.
  7. 12.7

    Personal data sent to model providers

    What we do
    Inventory the user data that reaches AI providers, redact what is not needed, and record each provider's data-processing terms.
    Why it matters
    For an AI app, the model provider is a second place customer data lives.
    How we check it
    Trace each model call, list the fields sent, and match them against the inventory.
  8. 12.8

    Subprocessor list

    What we do
    Publish the list of vendors that process customer data, with the agreement in place for each.
    Why it matters
    Every business customer's security questionnaire asks for it, and reviewers cross-check it against the privacy policy.
    How we check it
    Confirm the list matches the provider inventory and the privacy policy.

Handover, report & support

Handover & included support

Leave with the application, its operating instructions, and support for putting the handover to use.

7 checks · All included

Start with this part
  1. 13.1

    Production readiness report

    What we do
    Deliver the result for every scope item, the work completed, and its verification evidence.
    Why it matters
    Engineering work needs a record your team and reviewers can inspect.
    How we check it
    Account for all 123 IDs; keep failures visible until resolved and explain genuine non-applicable items.
  2. 13.2

    System architecture diagram

    What we do
    Show the deployed components, data flows, authentication boundaries, and third-party integrations.
    Why it matters
    New engineers and reviewers need to understand how the application fits together.
    How we check it
    Compare the diagram with the delivered environment and repository.
  3. 13.3

    Operating runbooks

    What we do
    Document deployment, rollback, key rotation, backup restoration, and the response to each operational alert.
    Why it matters
    The team needs usable procedures when an incident or release requires action.
    How we check it
    Walk through the runbooks against the delivered configuration and reference the rehearsal evidence.
  4. 13.4

    Live technical handover

    What we do
    Conduct and record a 60-minute walkthrough with the client team and technical advisors.
    Why it matters
    Documentation is more useful when the team can ask questions about operating the system.
    How we check it
    Deliver the recording, supporting documents, and answers or follow-ups from the session.
  5. 13.5

    Fourteen-day defect cover

    What we do
    Provide fourteen calendar days after handover to fix defects in the sprint deliverables at no additional engineering charge.
    Why it matters
    Issues discovered just after delivery need a clear route back to the team.
    How we check it
    Record the coverage dates, reporting channel, reproduction details, fixes, and retest results.
  6. 13.6

    Technical due diligence pack

    What we do
    Bundle the readiness report, architecture diagram, data model, security checklist, and capacity statement into one PDF.
    Why it matters
    Technical reviewers need an organized evidence pack rather than scattered files.
    How we check it
    Check the pack for completeness, consistent version references, and readable linked evidence.
  7. 13.7

    Thirty-day async access

    What we do
    Provide thirty calendar days after handover for questions about the delivered architecture, operation, and safe future changes.
    Why it matters
    Small questions often arise when the client starts using the handover independently.
    How we check it
    Provide the channel, access instructions, and the start and end dates in the handover.

What every check gets

A completed checklist has evidence behind it.

We inspect the existing implementation, correct what is incomplete or unsafe, and build the missing controls. Work that is already correct is tested and recorded rather than replaced unnecessarily.

Your handover report records each scope item, its implementation, and the check used to verify it.

  • Working

    We record the implementation and the passing verification result.

  • Does not apply

    We explain why the relevant system or condition is absent from your application.

  • Unfinished

    We keep it visible as unfinished work until it is corrected and retested. It does not become a paid upgrade or disappear into a recommendation list.

Load-test results specify the environment, data volume, workload, duration, and observed performance. Security test results specify what was tested and how.

See a sample readiness report

Sample case studies

See how we deliver the reports, and the depth we go into.

The full sprint

Ten working days, from code review to handover.

  1. Days 1–2

    Inspect and begin.

    We review the application, map its important workflows, and set up the environments needed to work safely. Implementation starts with the highest-priority access and data risks.

  2. Days 3–7

    Implement and test.

    We work through the scope and test the changes as we go. You receive clear updates on completed work and what comes next.

  3. Days 8–10

    Verify and hand over.

    We complete the security checks, workflow tests, load tests, and recovery drills. We review the results with you and walk your team through the delivered system.

At handover, you receive:

  • The updated codebase, tests, and deployment configuration.
  • A readiness report and technical due diligence pack.
  • Instructions for releases, backups, recovery, and incident response.
  • Guidance and automated checks for future AI-assisted changes.
  • A recorded 60-minute handover and a 20–30-minute codebase tour.

Your ten working days begin at the agreed kickoff, once the required repository and environment access is available. Production changes are coordinated with your team.

How it works

How the engagement works

First, a free audit call.

We look at what you’ve built and what you need it ready for. Before you commit, we’ll confirm how the published scope applies, explain the price, and agree on timing.

Something is broken now:
Message me on LinkedIn and say it’s urgent. We deal with it within 24 hours. If the problem is in an area we cover, we get it running safely first.
Start with one part:
If one part matters most right now, such as payments, your data, a launch or a sale, we can start there. We’ll talk it through on the call.
Third-party costs:
Hosting, paid tools and API usage are paid through your accounts. We explain any required costs before enabling them.
Start date:
Your agreed kickoff date, once repository access and the required environment credentials are available. We provide the access checklist beforehand.
Delivery:
By day ten, we demonstrate the verified application in staging, deliver the report and due diligence pack, and conduct the technical walkthrough. Production release is coordinated with your team through the included deployment process.
Included support:
Fourteen calendar days of defect cover and thirty calendar days of async questions, both beginning at handover.

Included in this sprint

  • Implementing and verifying the published production controls.
  • Correcting security, reliability and operational weaknesses covered by those controls.
  • Building supporting interfaces required by the scope, including session management, account deletion and billing self-service.

FAQs

Scope questions

What if I don’t know which parts my app needs?

You don’t need to work that out before booking. Tell us what your application does and what you need it ready for. On the first call, we’ll discuss how the scope relates to your situation. The detailed inspection of existing and missing controls happens during the sprint.

Can we start with just one part?

Yes. If one part matters most right now, such as payments, your data, a launch or a sale, we can start there. We’ll talk it through on the call.

My app is broken or down right now. Can you help?

Message me on LinkedIn and say it’s urgent. We deal with it within 24 hours. If the problem is in an area we cover, we get it running safely first.

Are the recovery drill, penetration testing, and due diligence pack extra?

No. All 123 deliverables are included in the sprint. There is no advanced tier to unlock them.

What if a control is already implemented?

We inspect and test it. If it is correct, we record the evidence. If it is incomplete, we fix it. The sprint includes verification of existing work as well as implementing missing controls.

What if our application does not use Stripe or PostgreSQL?

We apply the equivalent controls for your payment provider, database, and framework. The list describes the production capability we deliver; the implementation follows your stack.

More questions
Are the security tests an independent certification?

The targeted security tests are performed by AxonBuild and cover the five priority attack surfaces documented in your report. The package also includes the OWASP review and a controls checklist with evidence.

What does the privacy work cover?

We implement and document the technical data-handling controls listed above and check that the application's behavior matches its published data practices.

Does the scope include new screens?

It includes the supporting interfaces needed for the listed controls, such as session management, account deletion, and billing self-service.

What if a test fails?

We address the failure and retest it. The report keeps unresolved work visible, and final acceptance requires the applicable scope to be verified.

What could change the ten-working-day delivery date?

The delivery date moves by the time work is blocked by missing access, delayed approvals, or changes your team makes to the agreed code during the sprint. We explain the impact and confirm the revised date with you.

What does the post-handover support cover?

After handover, your team operates the application and receives its alerts. Our included cover is 14 calendar days of fixes for defects in the delivered work and 30 calendar days of questions about the handover and architecture.

Meet the person on the call
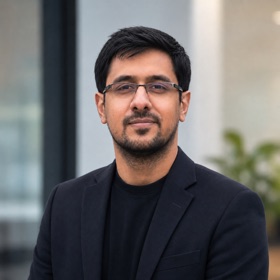
Your free 30-minute audit

Bilal Shahid, Co-founder, AxonBuild
Bilal ShahidCo-founder, AxonBuild “Hi, I’m Bilal. You’ll talk to me, not an AI. Promise.” See my work on LinkedIn
  1. Show us your app and tell us what’s coming next. Nothing technical needed.
  2. We look at it with you and point out the biggest risks we can see, in plain words.
  3. You leave knowing what to fix first. It’s yours to keep, whether you work with us or not.
Book a free audit

No pressure. If you want our help after, we tell you what it costs.

Let’s talk about your app

Let’s make sure your app holds up.

Book a free 30-minute audit. We look at your app with you and tell you what to fix first.

Book a free audit

No commitment. Nothing technical needed.

Not a call person? Message me on LinkedIn

Sample case study ·